

Next Session
Beyond Guardrails: A Technical Deep Dive into AI Model Safety, Agent Safety & Governance
As AI moves from generating answers to autonomously taking actions, safety changes fundamentally. Model alignment is only one part of the problem. Agents introduce planning, uncertainty, memory, tools, permissions, and entirely new failure modes.
- Why model safety and agent safety are fundamentally different, and where model-level alignment stops being enough.
- How uncertainty, long-horizon planning, and partial observability can cause autonomous agents to make unsafe decisions.
- How to architect safety when the intelligence itself is probabilistic and non-deterministic.
- How to evaluate, govern, and establish trust in increasingly autonomous AI systems.
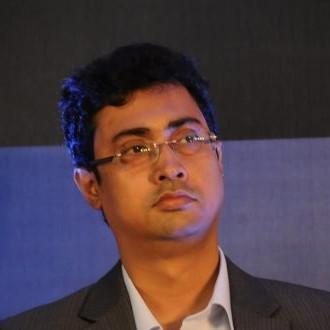
Arnab Chattopadhayay
Co-founder & Distinguished Scientist, FireCompass
Thursday, Sep 10, 2026
9:00 PM IST · 11:30 AM ET · 7:30 PM GST